Make an AI talking avatar from one photo.
No camera, no booking. Give a portrait a script and a voice and it performs — in any language, for as long as the audio runs. For ads, training, localization, and the presenter inside your own product.
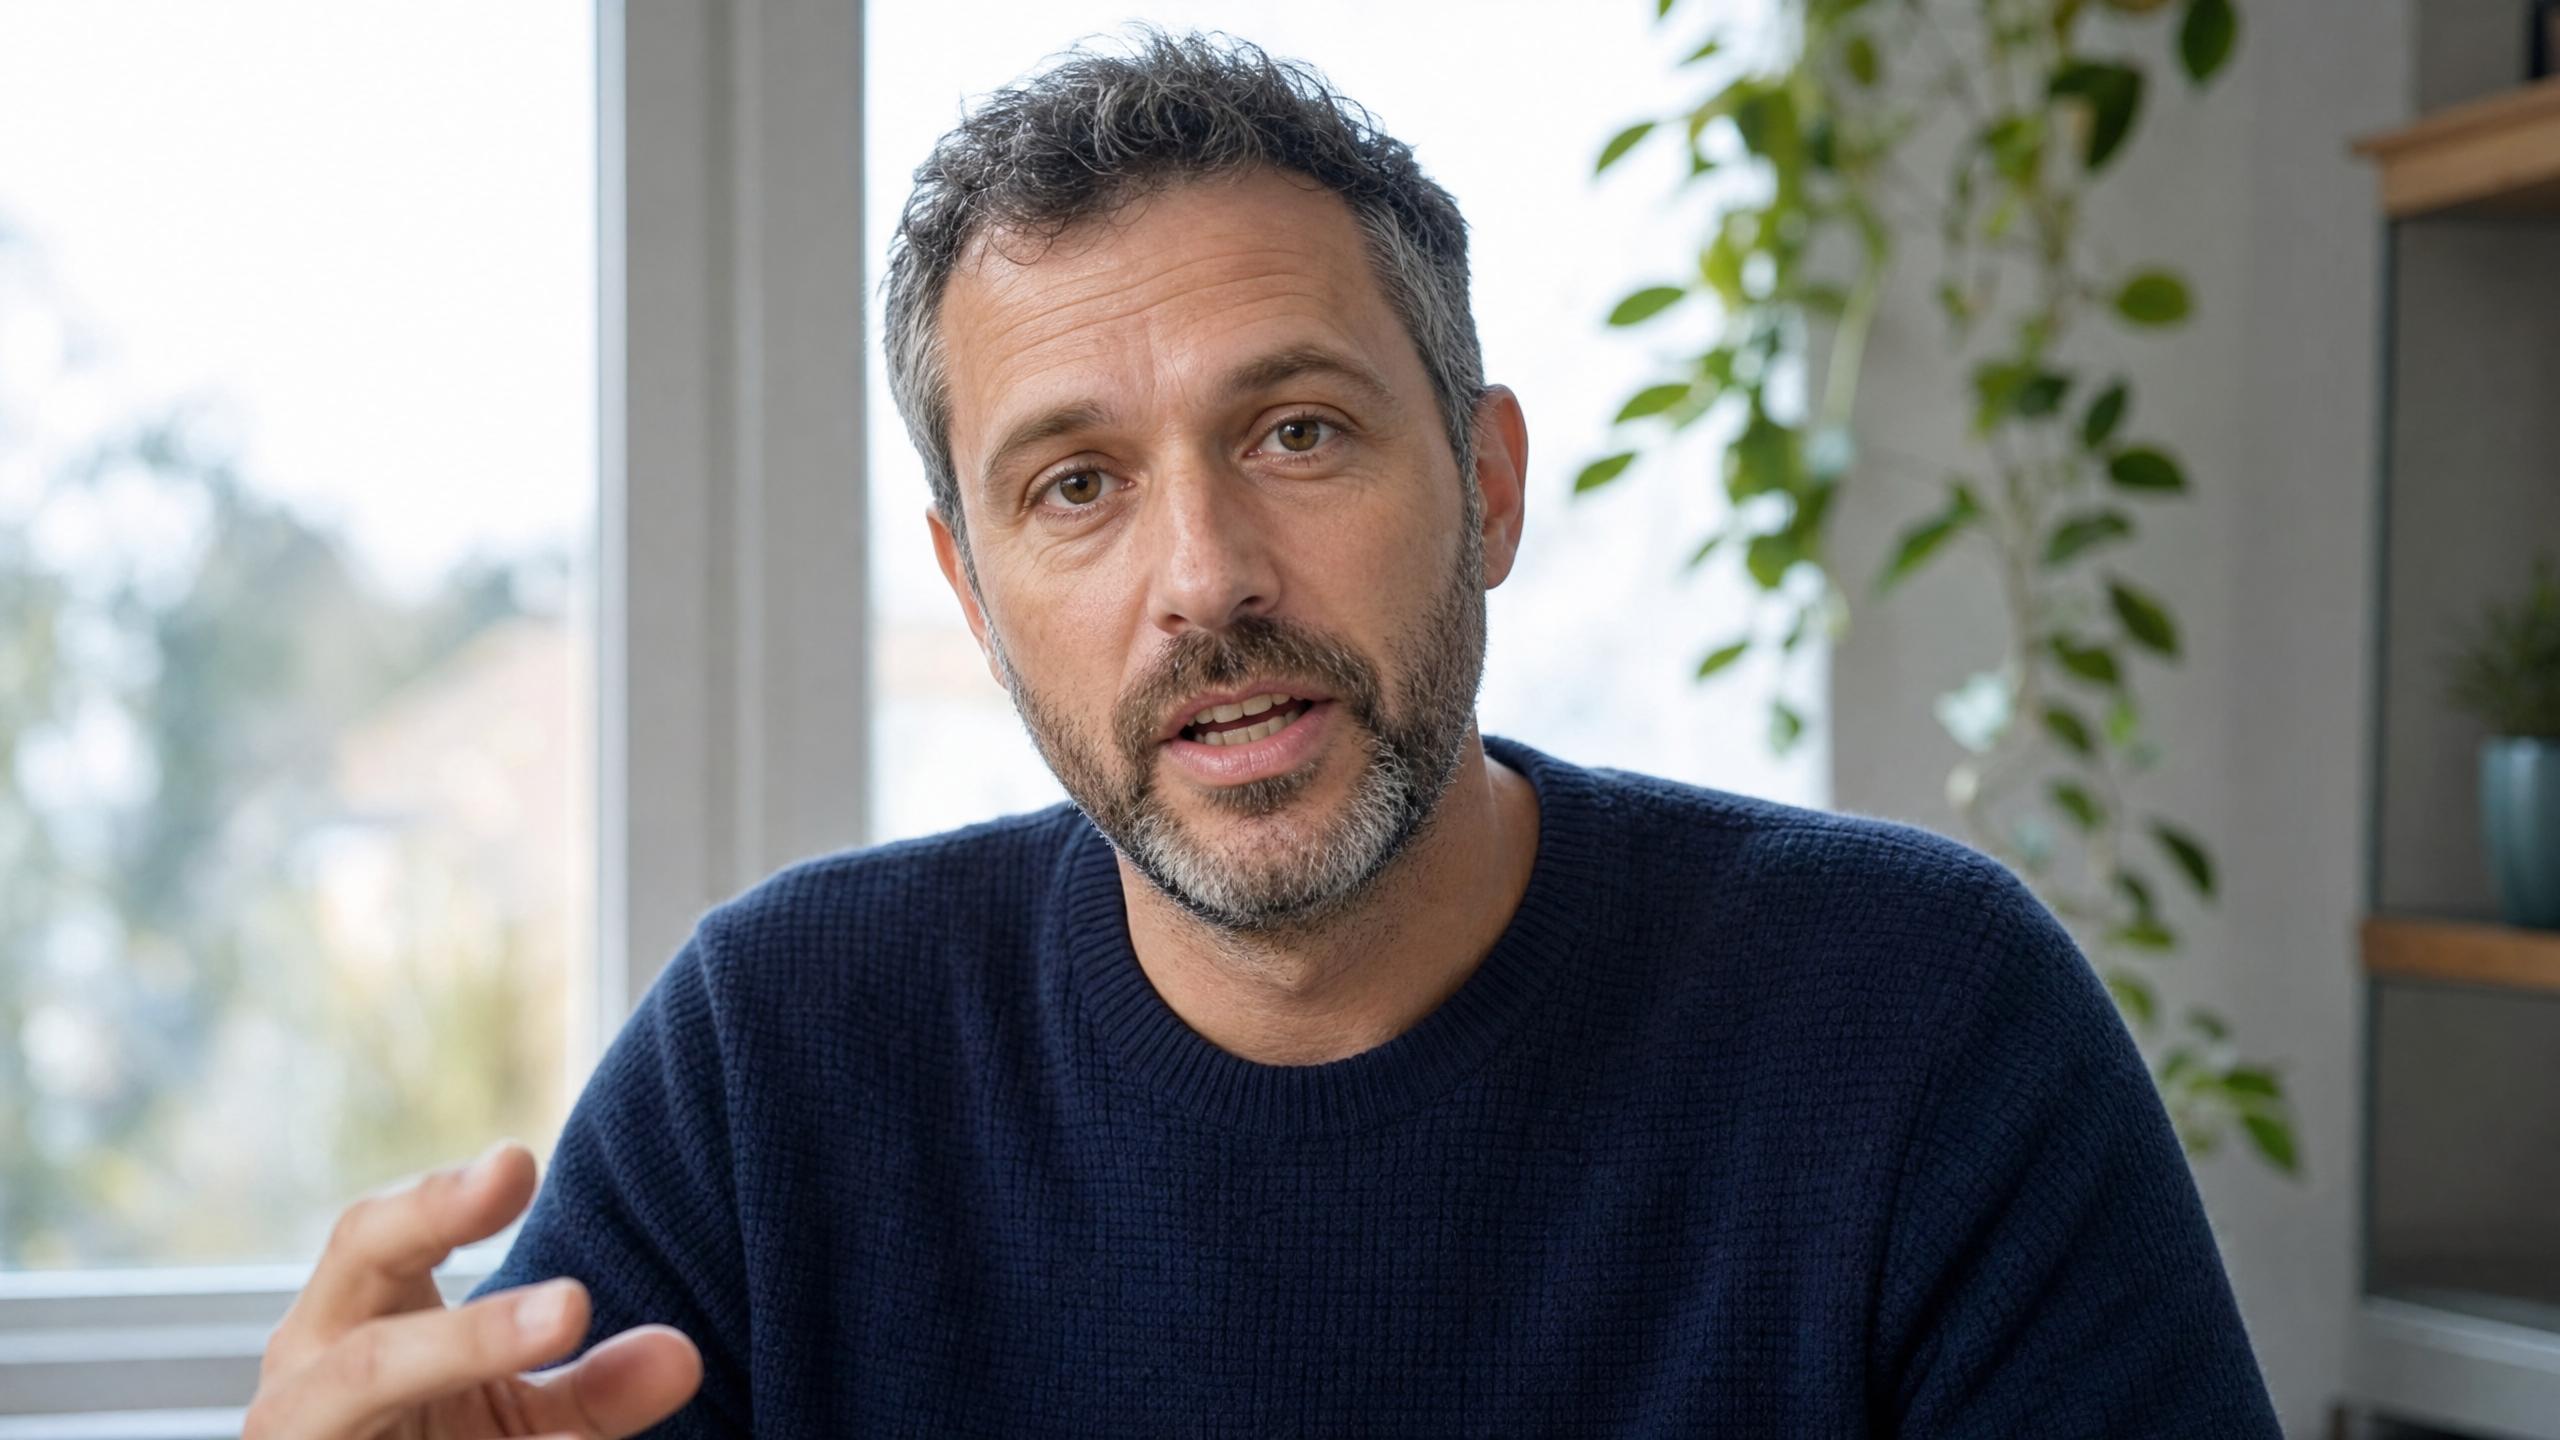
"We rebuilt onboarding this quarter. Let me show you what changed."
The same person, on demand.
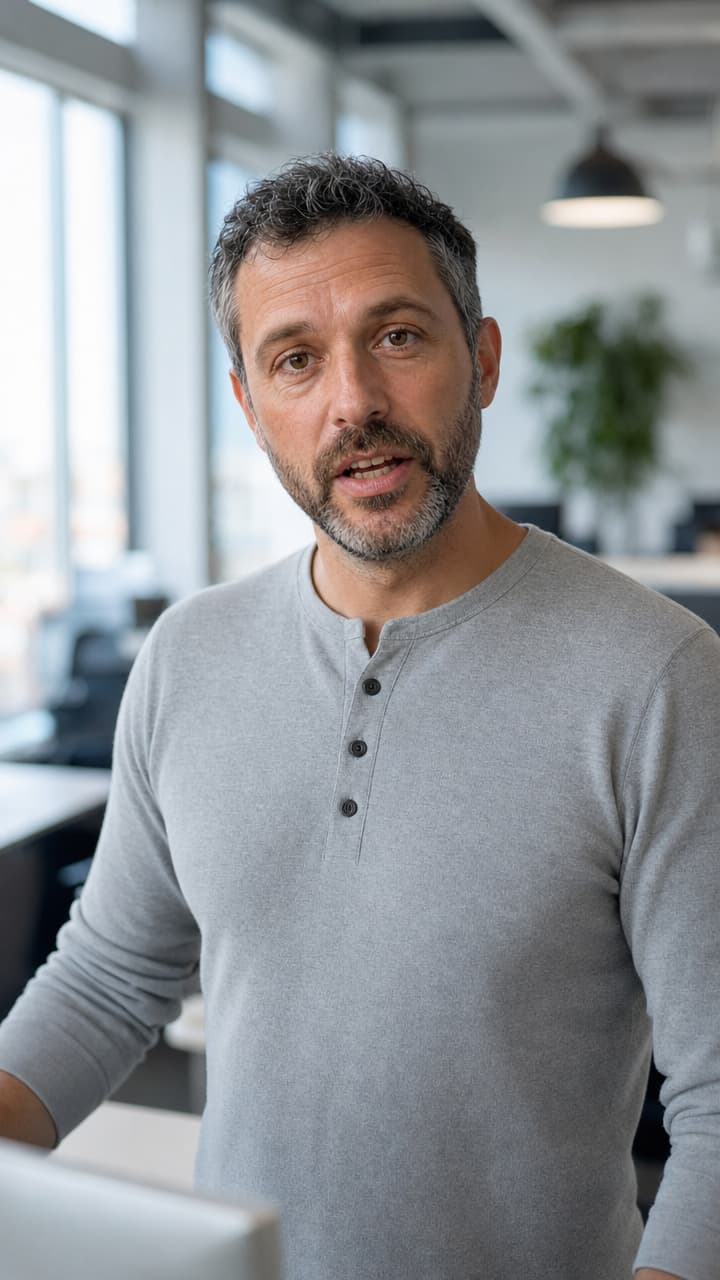
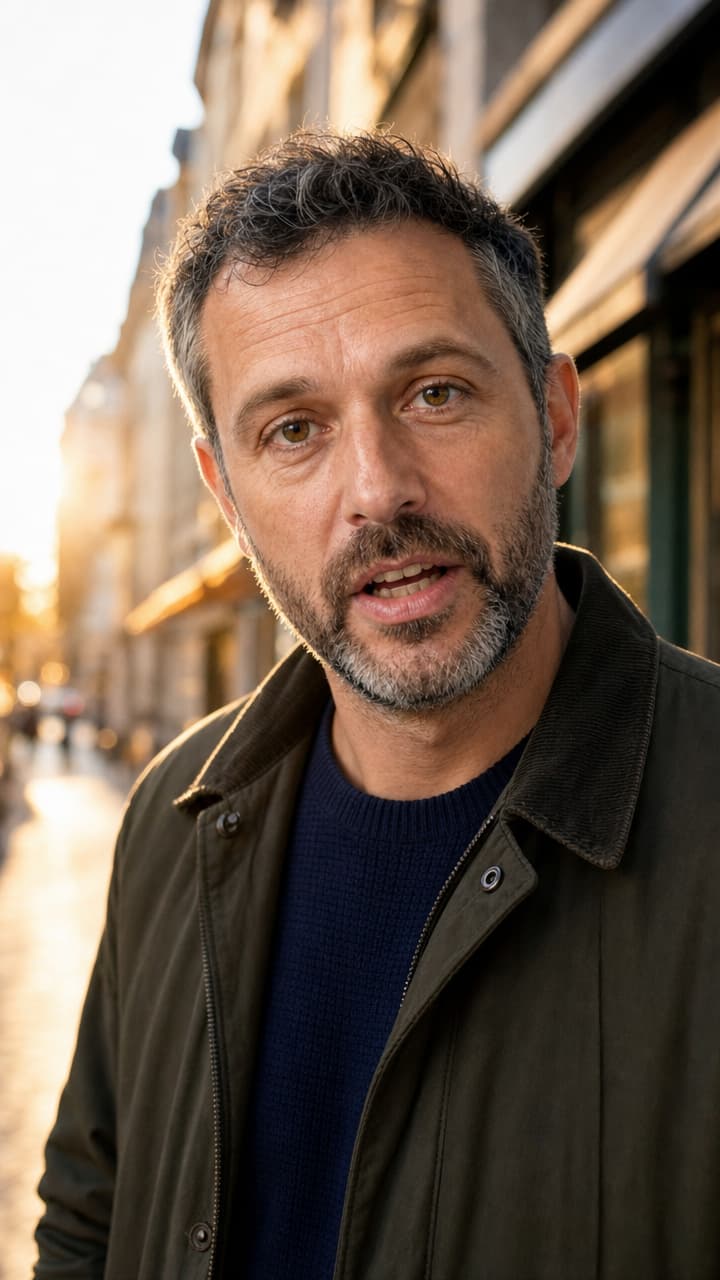
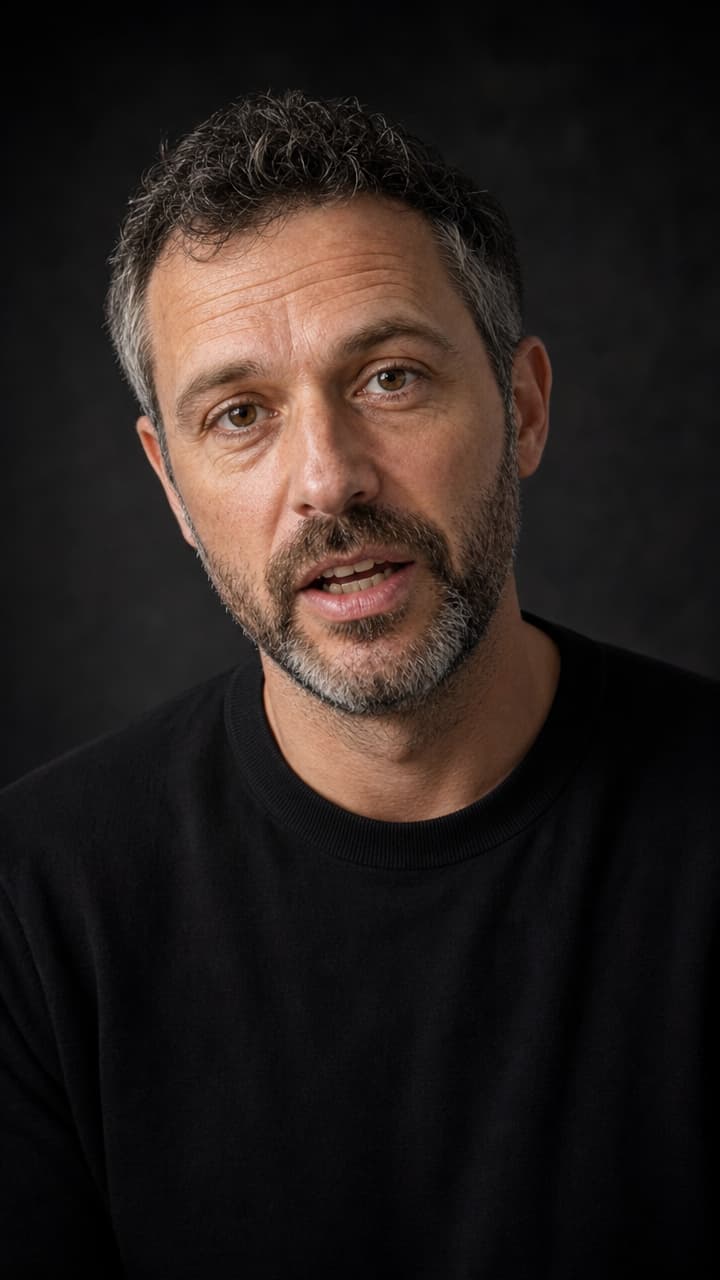
The same face, every take.
Lock the portrait once and it holds — through a script you rewrote this morning, a module you add next month, a market you open next quarter. That's what turns a clip into a spokesperson: a campaign, a course, or the presenter inside your own product can all wear the same face without a second shoot. It's also what makes testing cheap, because ten hooks for TikTok, Reels and YouTube cost ten renders rather than ten shoots.
Every market, the same face.
Swap the audio and keep the person. The same portrait delivers your script in whatever language the market speaks, so localization stops being a reshoot and becomes a file you drop in — a voice you picked in Studio, or another audio URL in the request.
Two people, one frame.
Point one portrait at one audio track and you get a presenter. Point a two-up frame at two — one per speaker, marked by where each sits — and you get a conversation, each voice landing on its own face with nothing to cut between. Interviews, role-plays, the awkward support scenario every onboarding course needs.
Every avatar and every voice, under one key.
Built for visual inference.
Serving video is a different problem from serving text — a single request can saturate a GPU, and none of the tricks that made language models cheap apply. Hedra's engine was built for exactly that workload.
Whichever model you choose — ours or anyone else's — it runs on the same infrastructure, tuned for visual inference and priced per second of output.
Generate with API or Agent
Build with the API
One key, every model, priced per second of output.
Make one now.
No code — bring a photo, type the script, pick a voice, export the result.
FAQs
No. Bring a photo of whoever should present, or generate the character first and use that — the avatar models take a still either way, so nothing has to be filmed and nobody has to be booked.
Generate a character →