Turn text into video with AI.
Describe a scene in plain language and get finished footage back — for ads, product video, localization, and the video features inside your own app.
"A lighthouse keeper pours tea while the beam sweeps through fog."
Built for real production.
Footage that stays on script.
Write the scene like you'd brief a director — subject, light, camera move — and the footage holds the intent. On the fiftieth generation as much as the first, which is what keeps a campaign, a catalog, or a video feature inside your app from drifting off-brief.
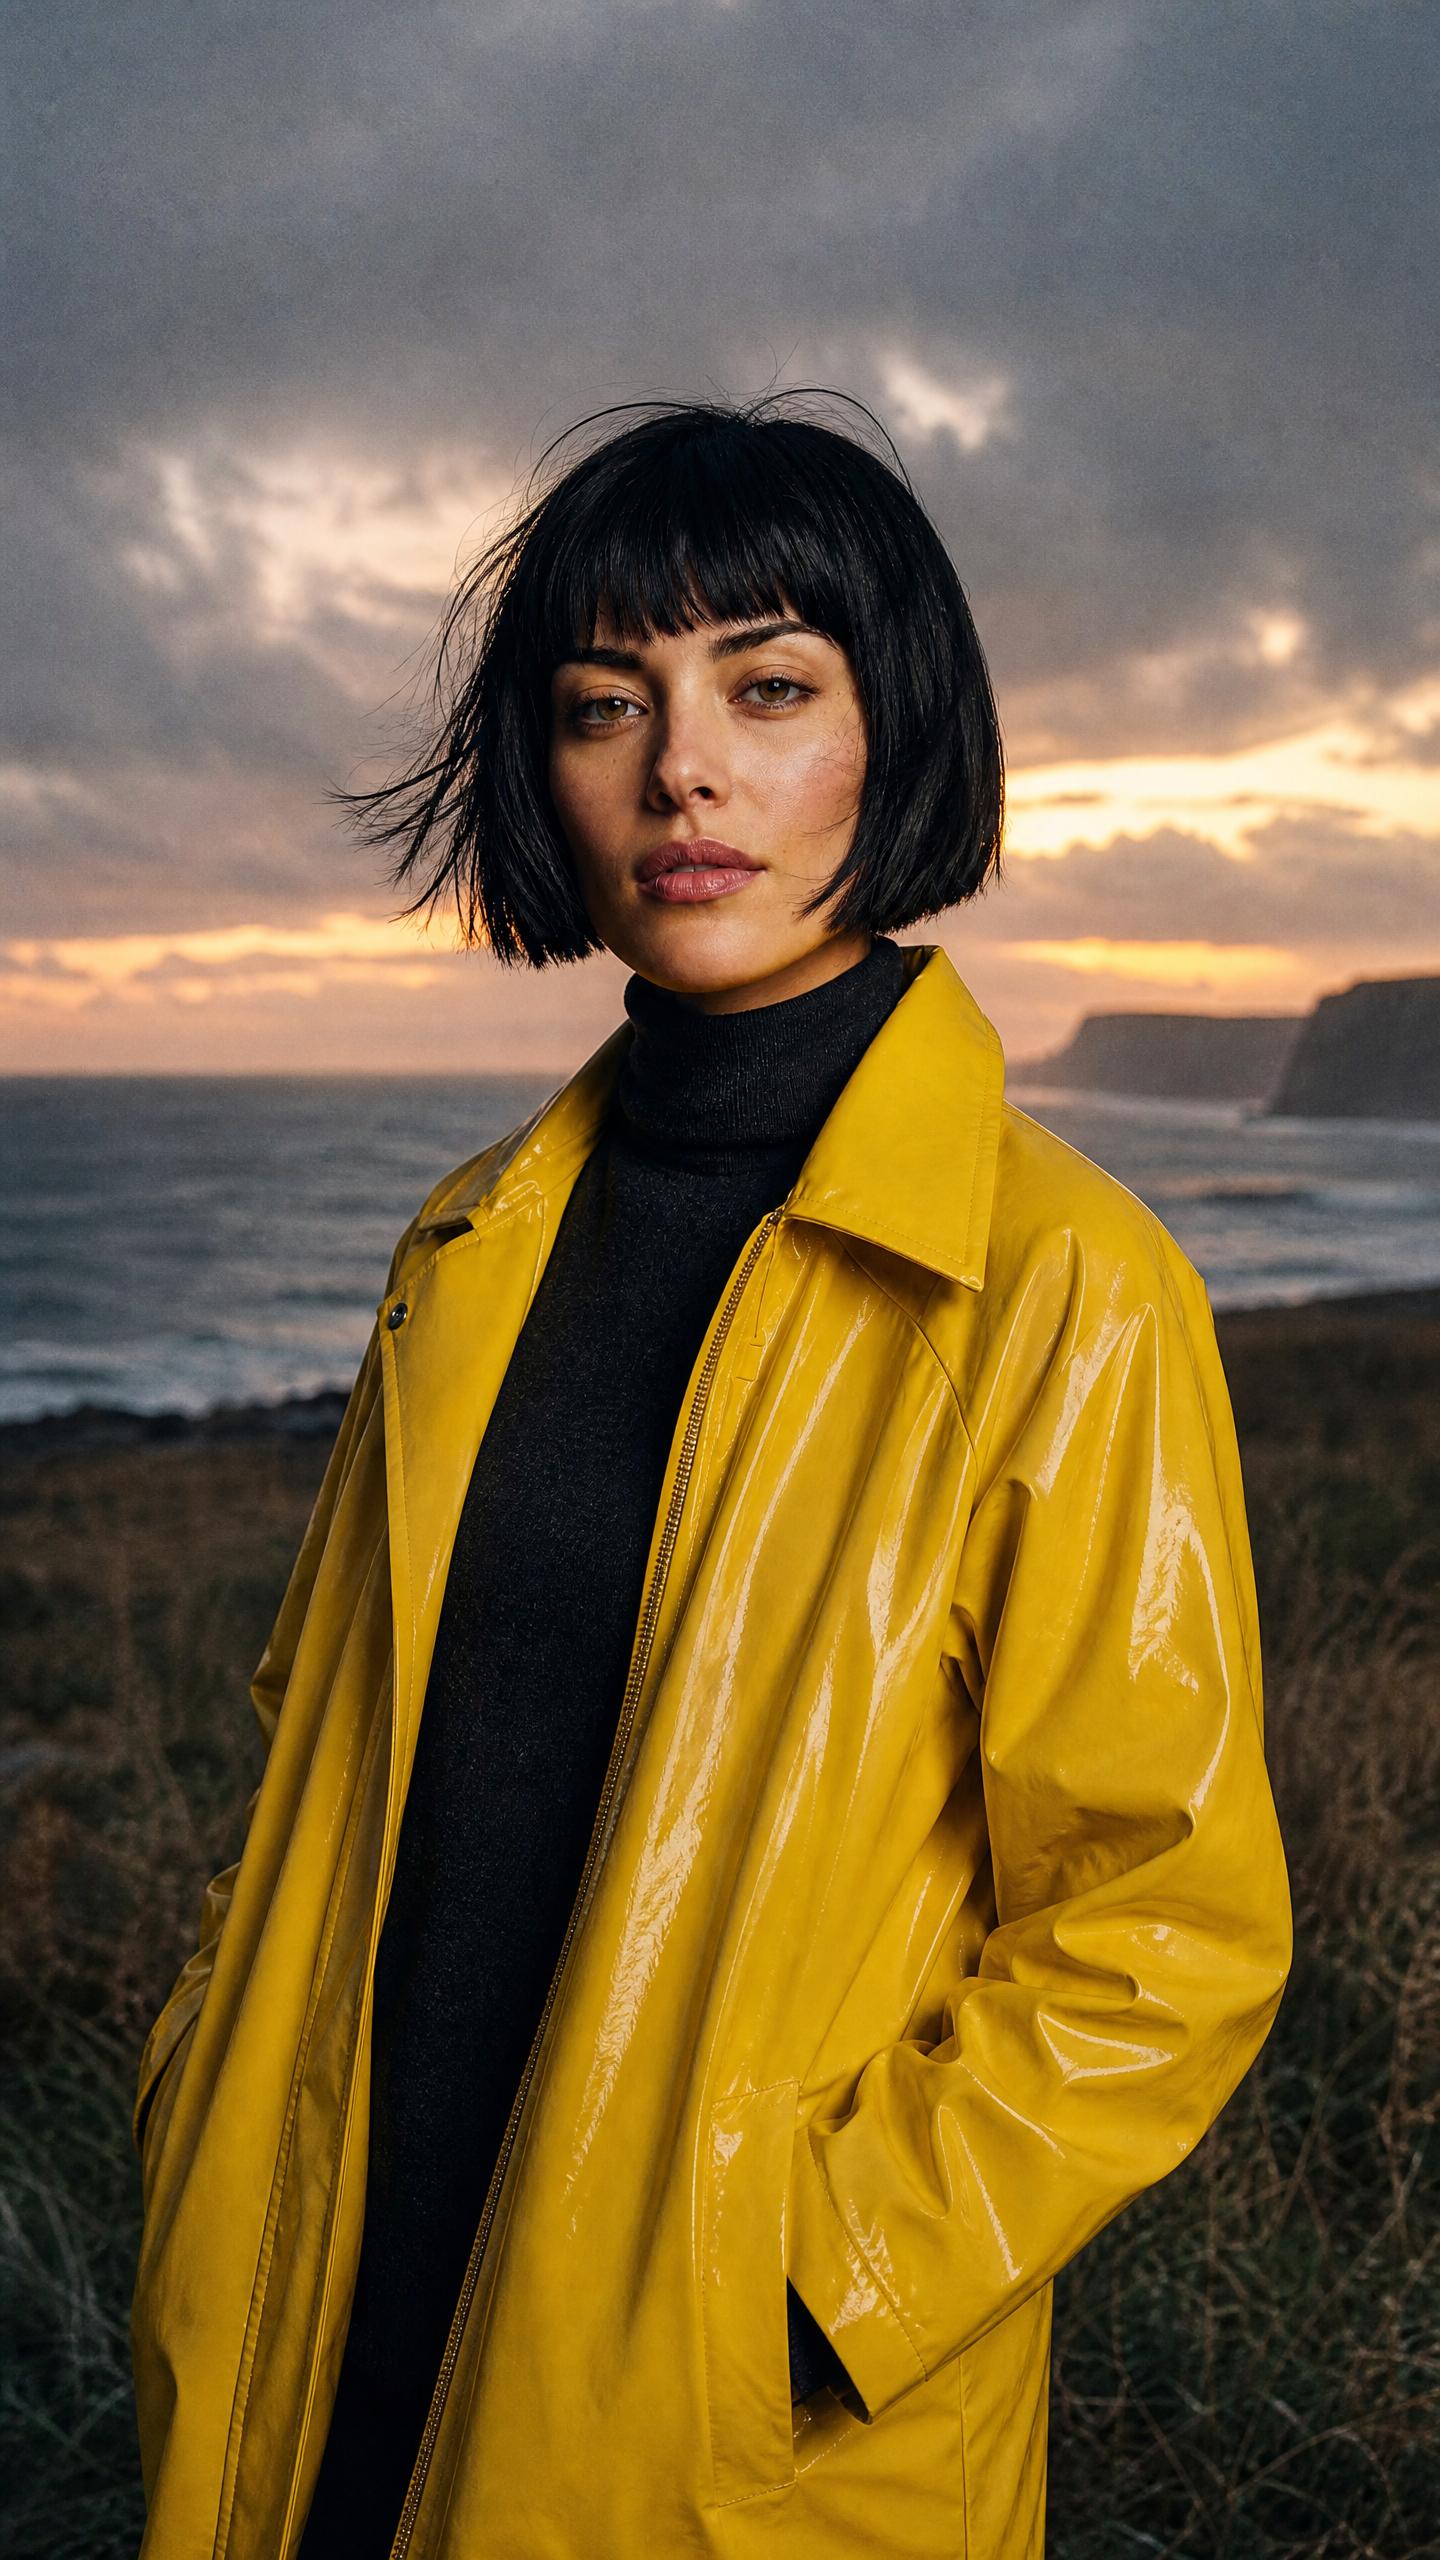
One subject, every shot.
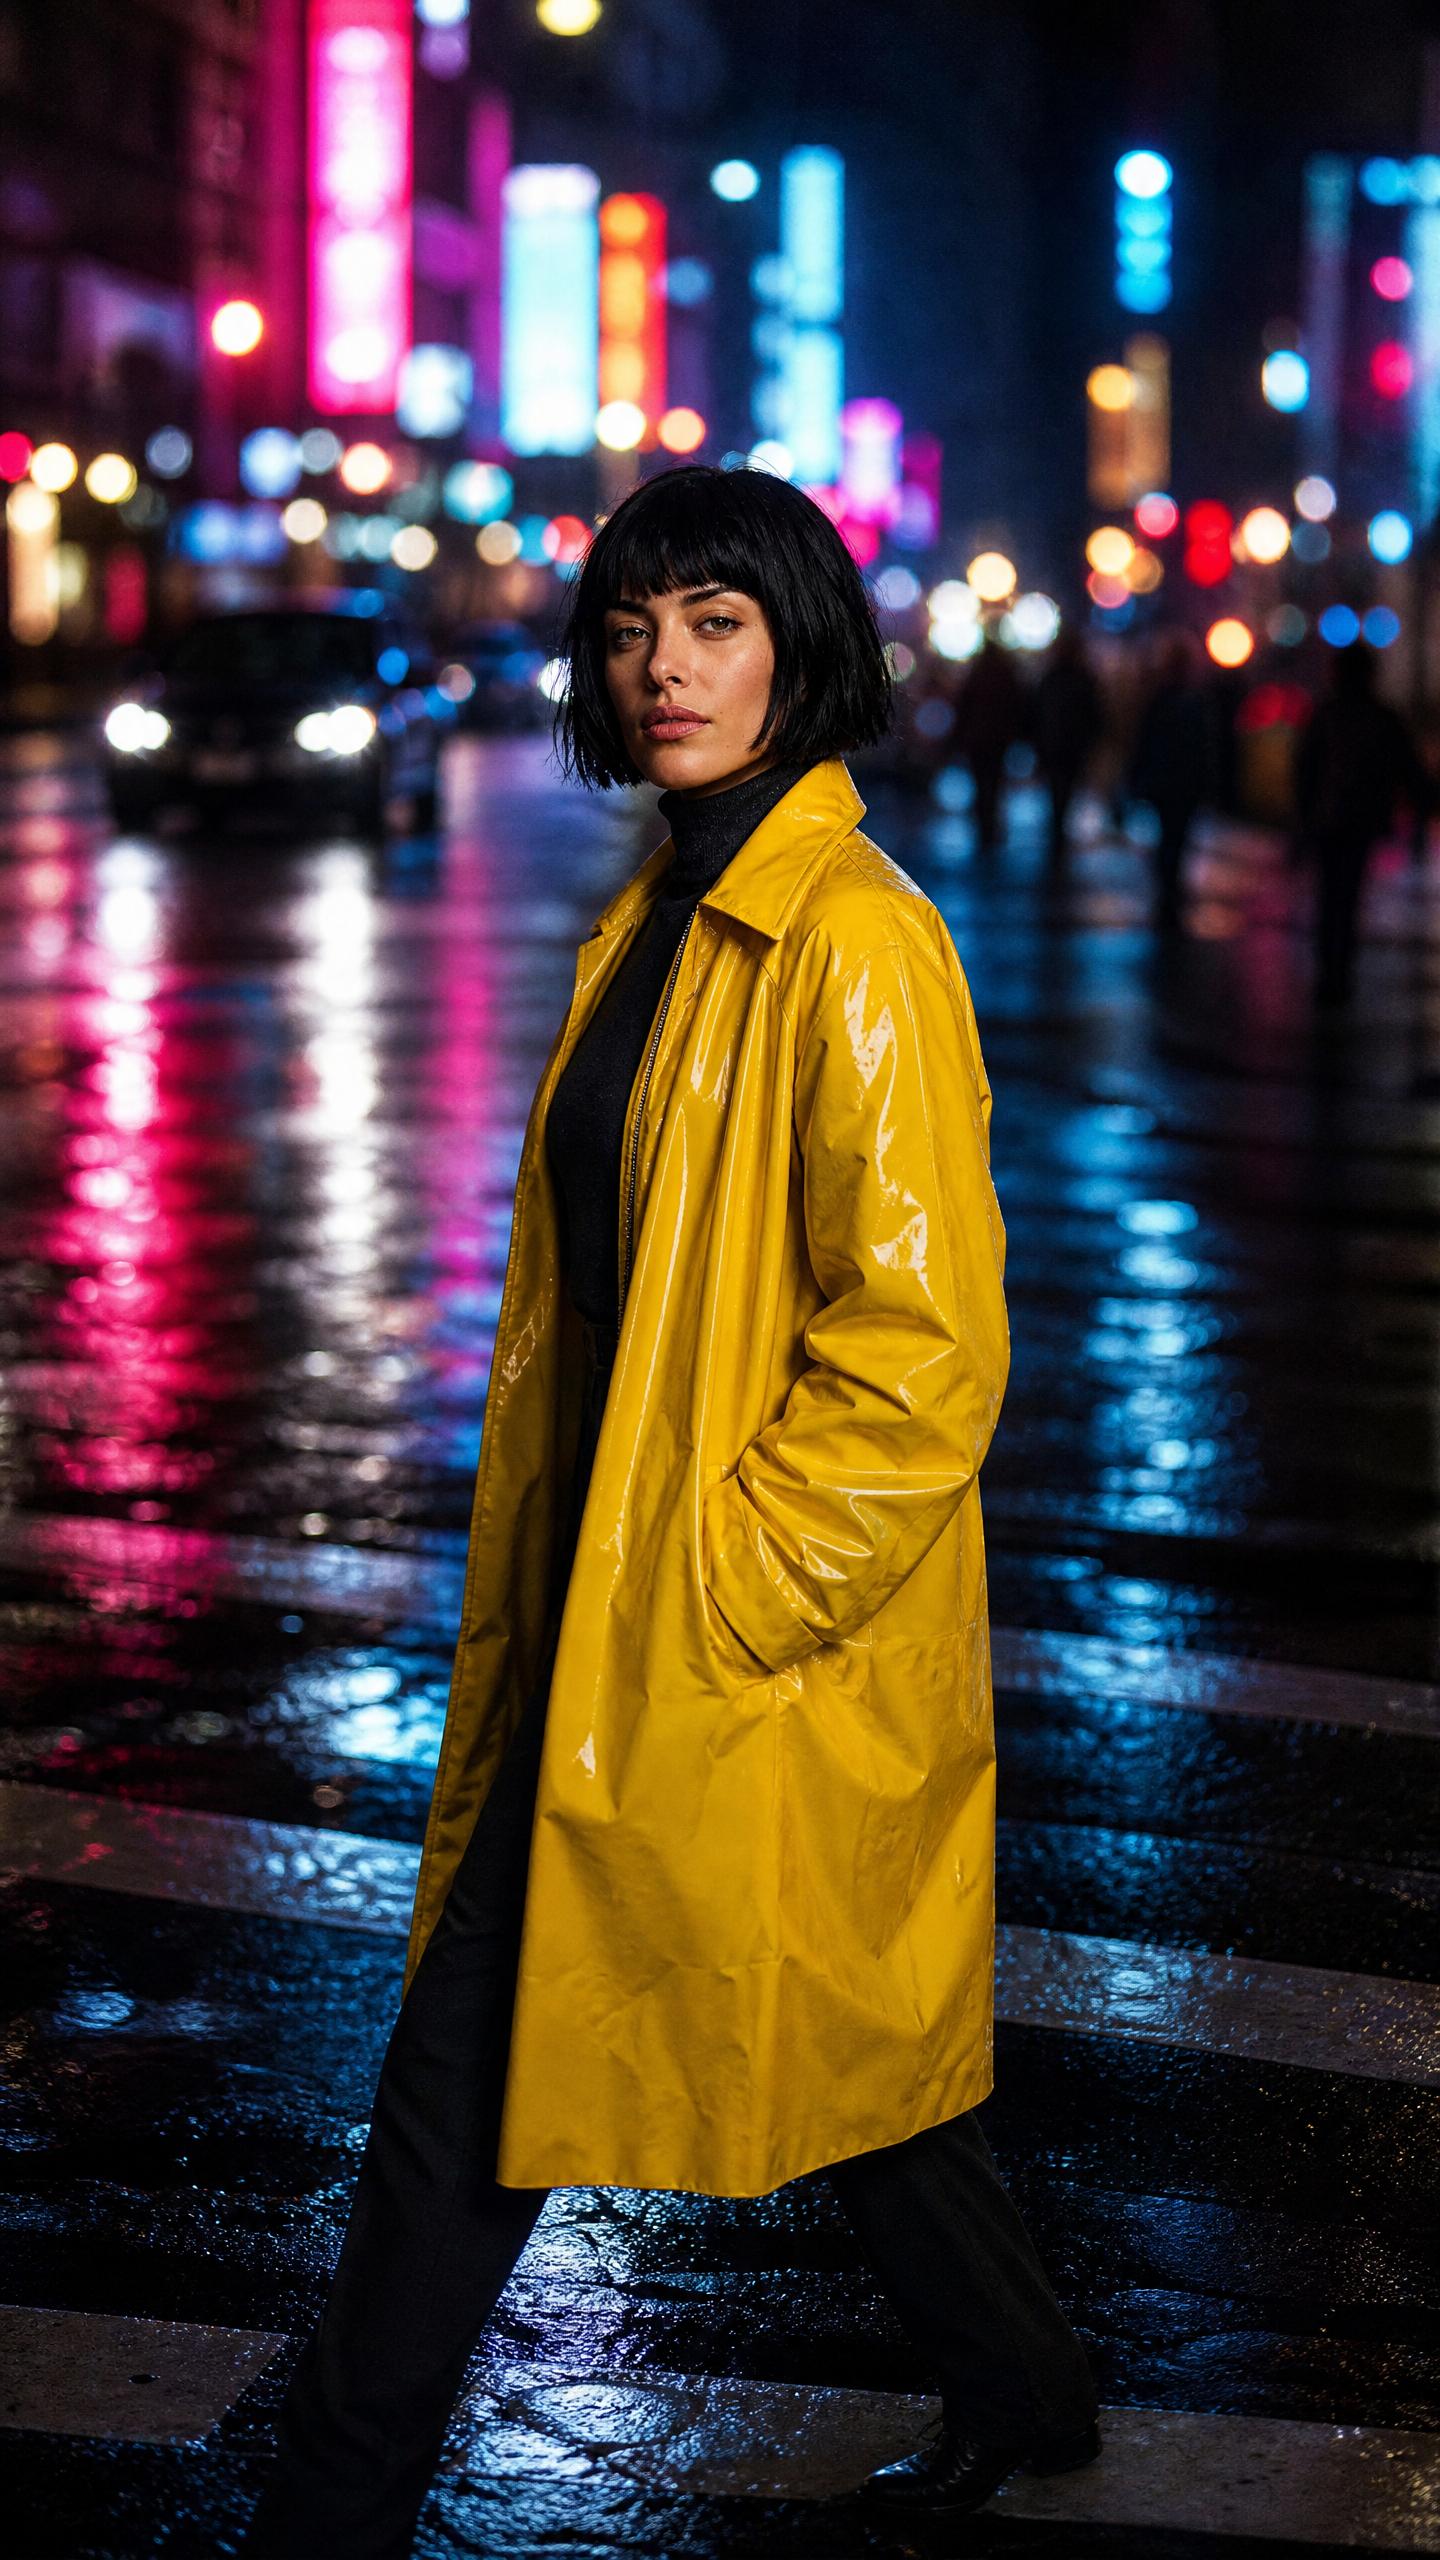
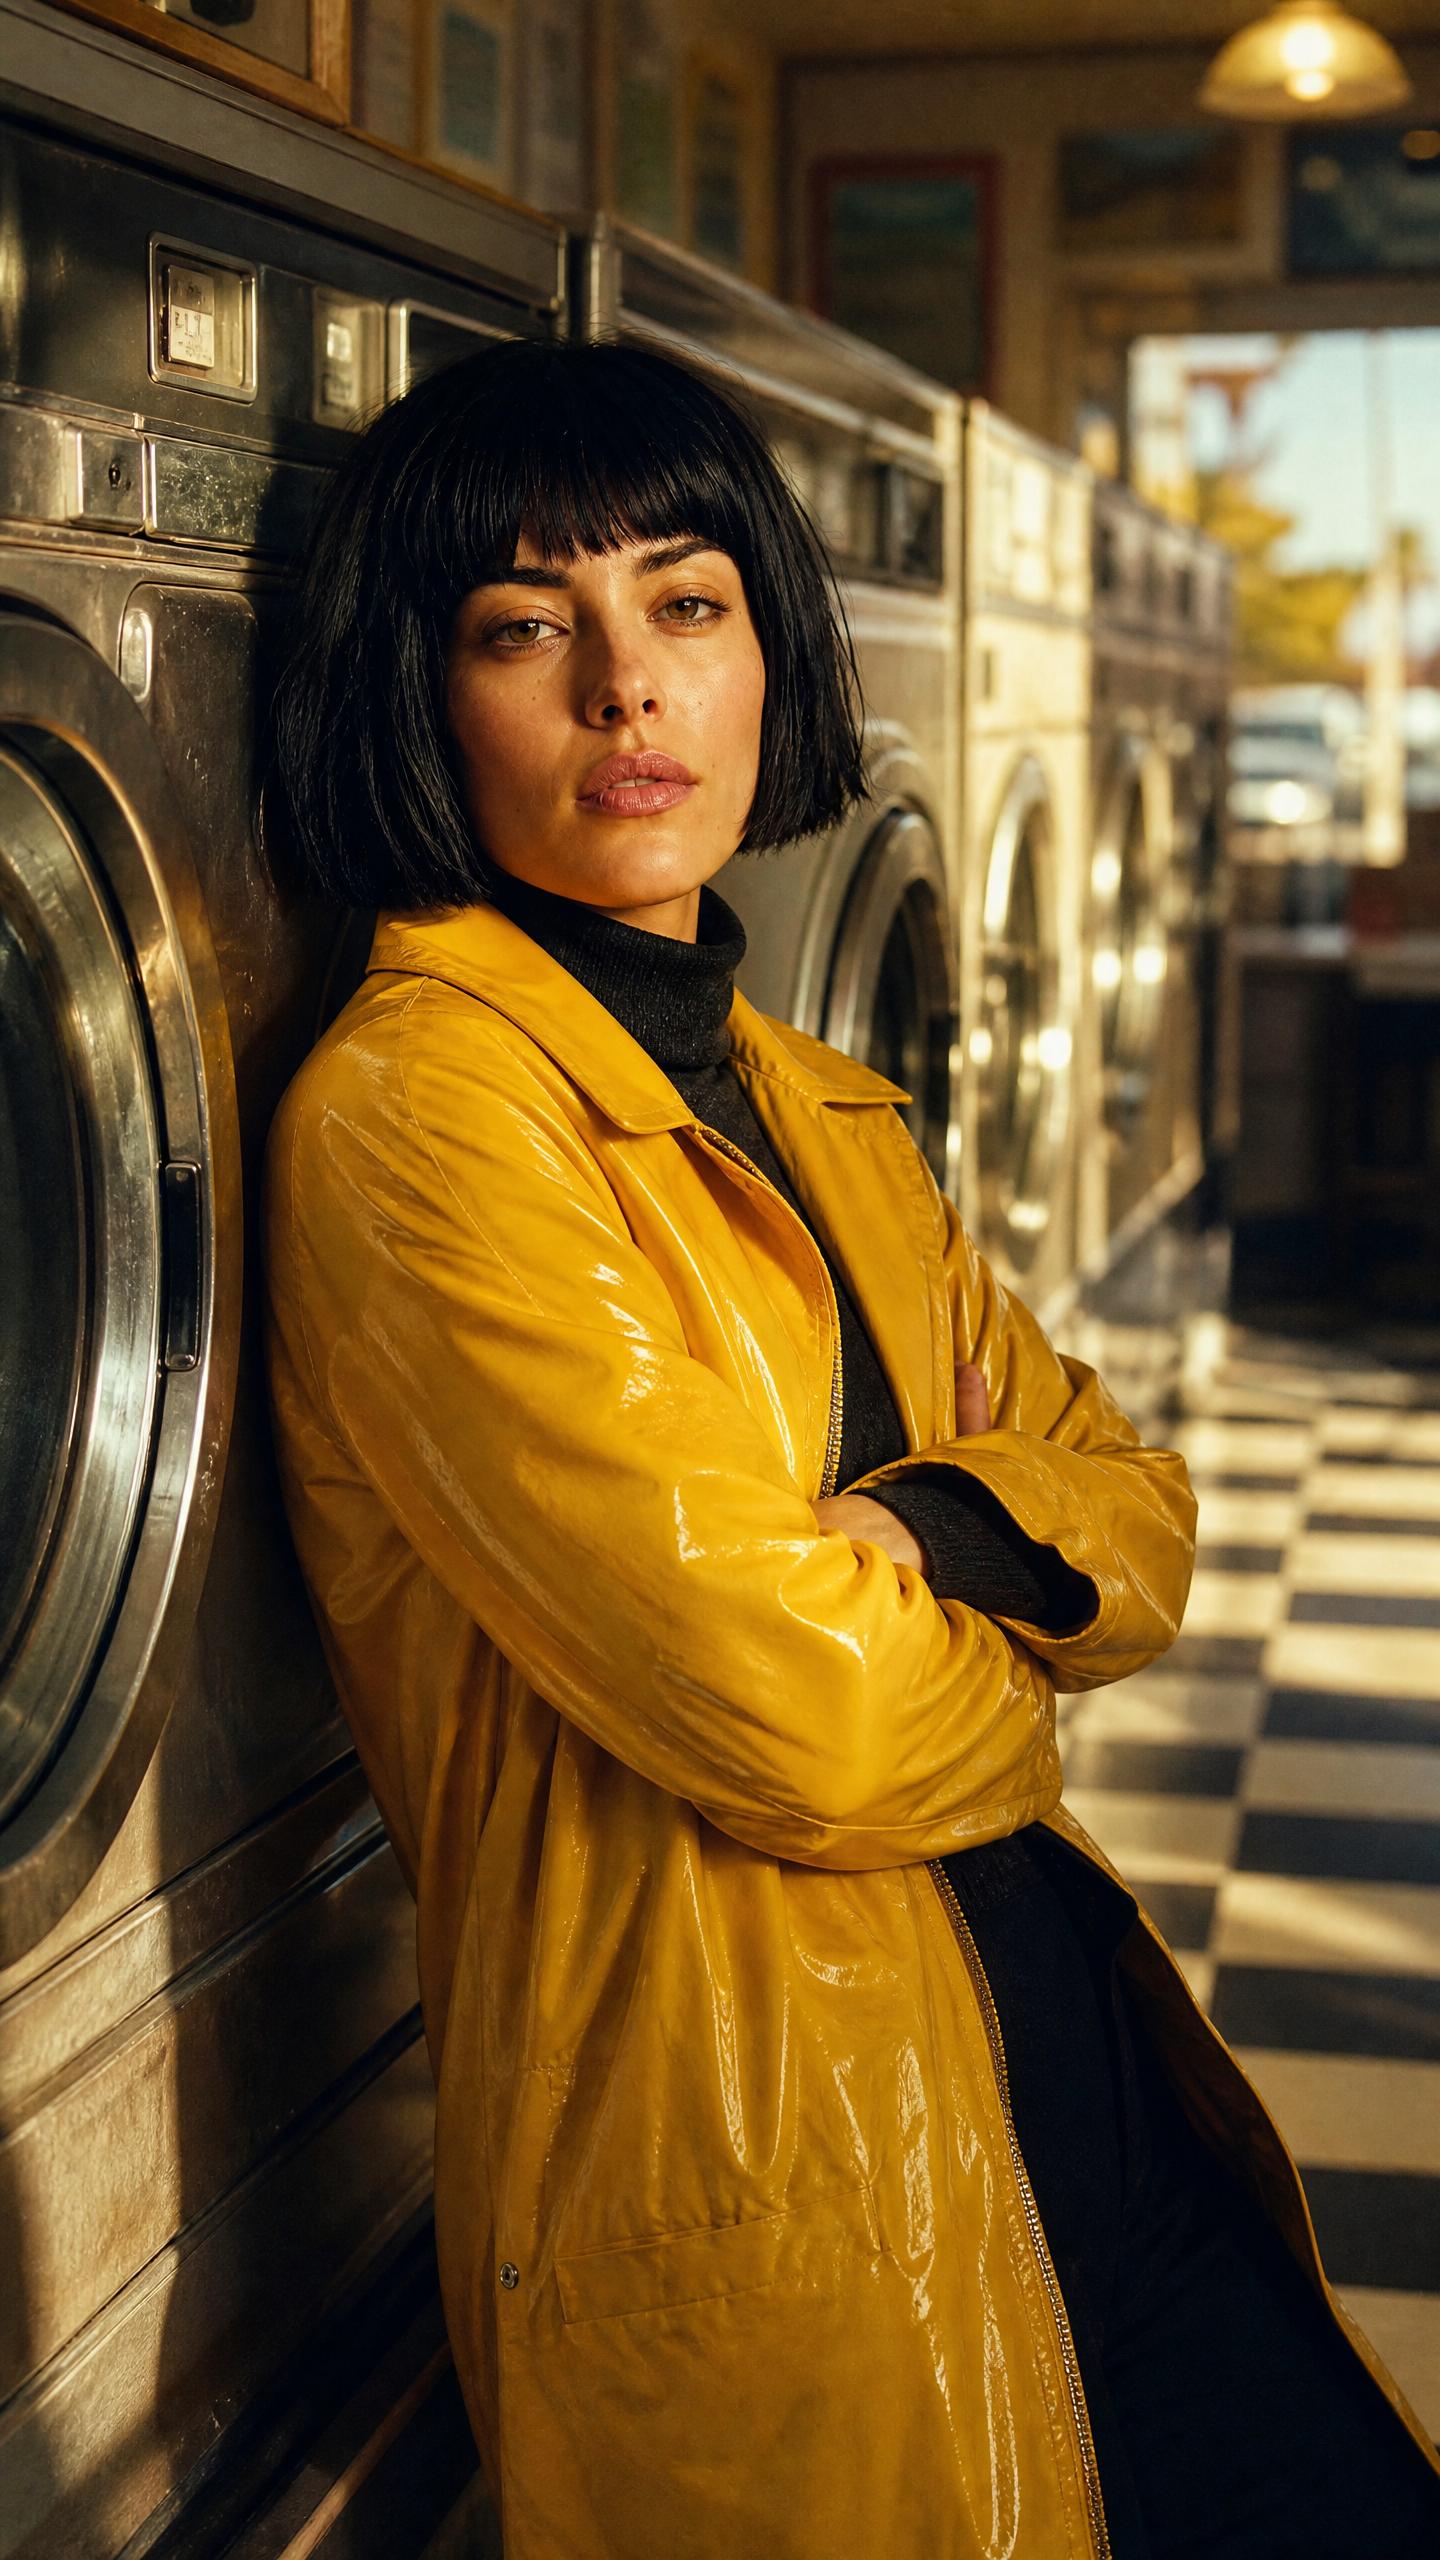
Lock a character or a product once, then restage it anywhere — new scene, new style, same face. It's the difference between a pile of clips and a catalog, a series, a brand.
Shots that speak.
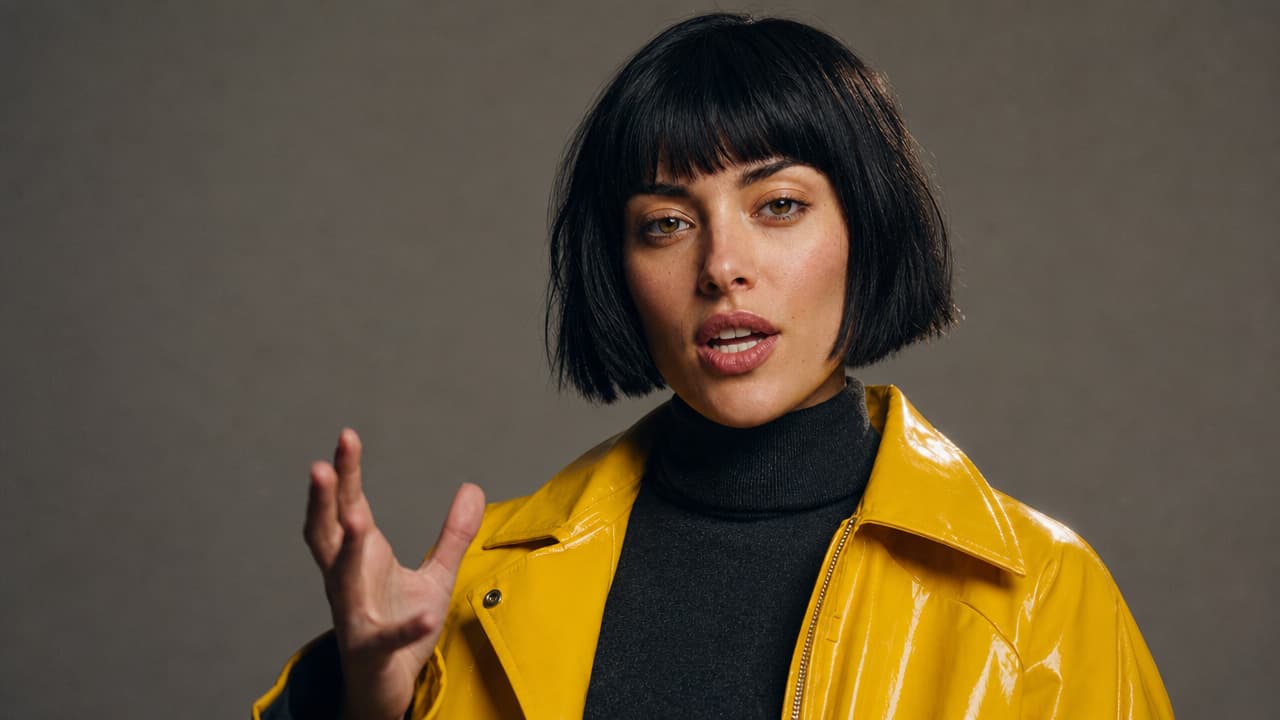
Give a character the line and a voice — any language — and the performance lands on every frame. One take becomes ten markets: same face, same voice, different words.
The right model for every shot.
Different shots want different models, ours and everyone else's. Let the agent route each one or pick it yourself — in Studio it's a dropdown, in a request it's a string, and it's priced per second either way.
 OMNIA
 HAILUO
 VEO 3.1
 OMNIA
 SEEDANCE
 KLING 3
 HAILUO
Built for visual inference.
Serving video is a different problem from serving text — a single request can saturate a GPU, and none of the tricks that made language models cheap apply. Hedra's engine was built for exactly that workload.
Whichever model you choose — ours or anyone else's — it runs on the same infrastructure, tuned for visual inference and priced per second of output.
Generate with API or Agent
Build with the API
One key, every model, priced per second of output.
Generate it now.
No code — type the scene and export the result. Your prompt carries over when you sign up.
FAQs
Every leading text-to-video model, ours included — each with its specs, per-second rate, and a runnable example in the model directory. New models land there as they release.
Browse all models →